PUBLICATIONS / RESEARCH RECORD
Ideas, methods,
and the evidence behind them.
Browse three connected research areas separately, then refine by year, status, authorship, and publication type. Each entry is written at two levels: a fast plain-language takeaway and the technical record.
New Scholar records awaiting curation Checking Scholar snapshot…
Automatically indexed records are shown with minimal metadata until their venue, authorship, contribution, and public evidence are manually verified.
Newest first · status shown explicitly
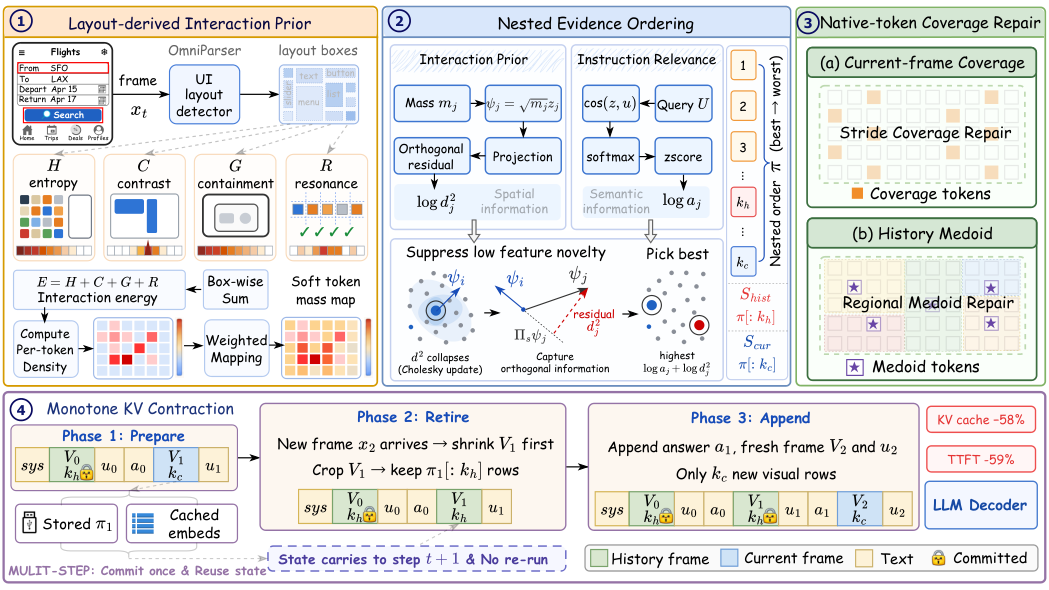
TRACE: Trajectory-robust Admission with Evidence Ordering for Efficient GUI Agents
arXiv preprint
A training-free GUI-agent framework for irreversible visual-token admission that remains useful for unknown future targets while preserving coverage of operable regions.
Why this work matters
Ranks visual evidence with layout-derived interaction priors, instruction relevance, and feature novelty; repairs spatial coverage into a nested token order; and contracts retired frames with monotone KV contraction.
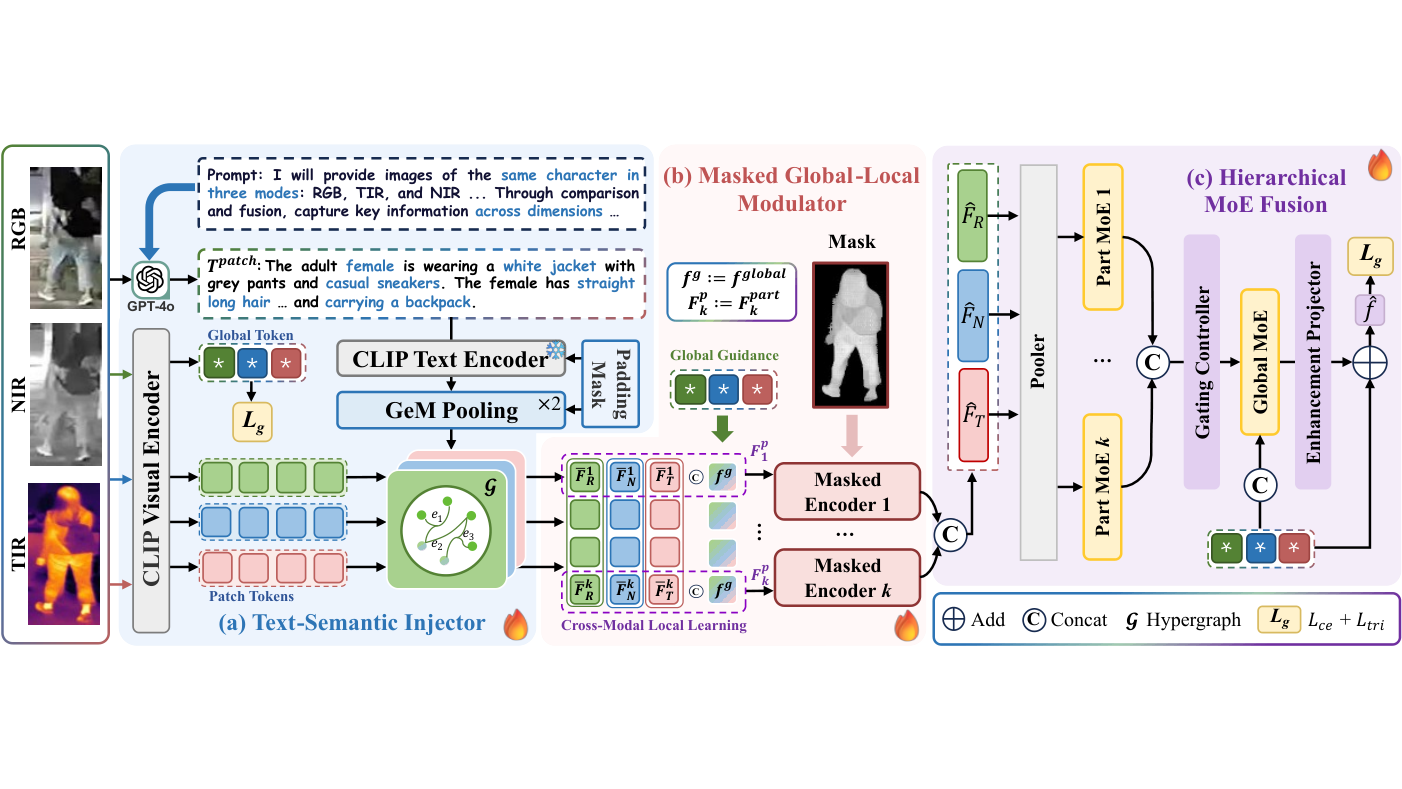
Multi-Modal Object Re-Identification with Dual Semantic Guidance and Global-Local Mutual Modulation
IEEE Transactions on Circuits and Systems for Video Technology (TCSVT)
Dual semantic guidance and global-local modulation improve part-level alignment and hierarchical multimodal aggregation.
Why this work matters
Combines unified text semantics, soft-mask local modulation, and hierarchical mixture-of-experts fusion.
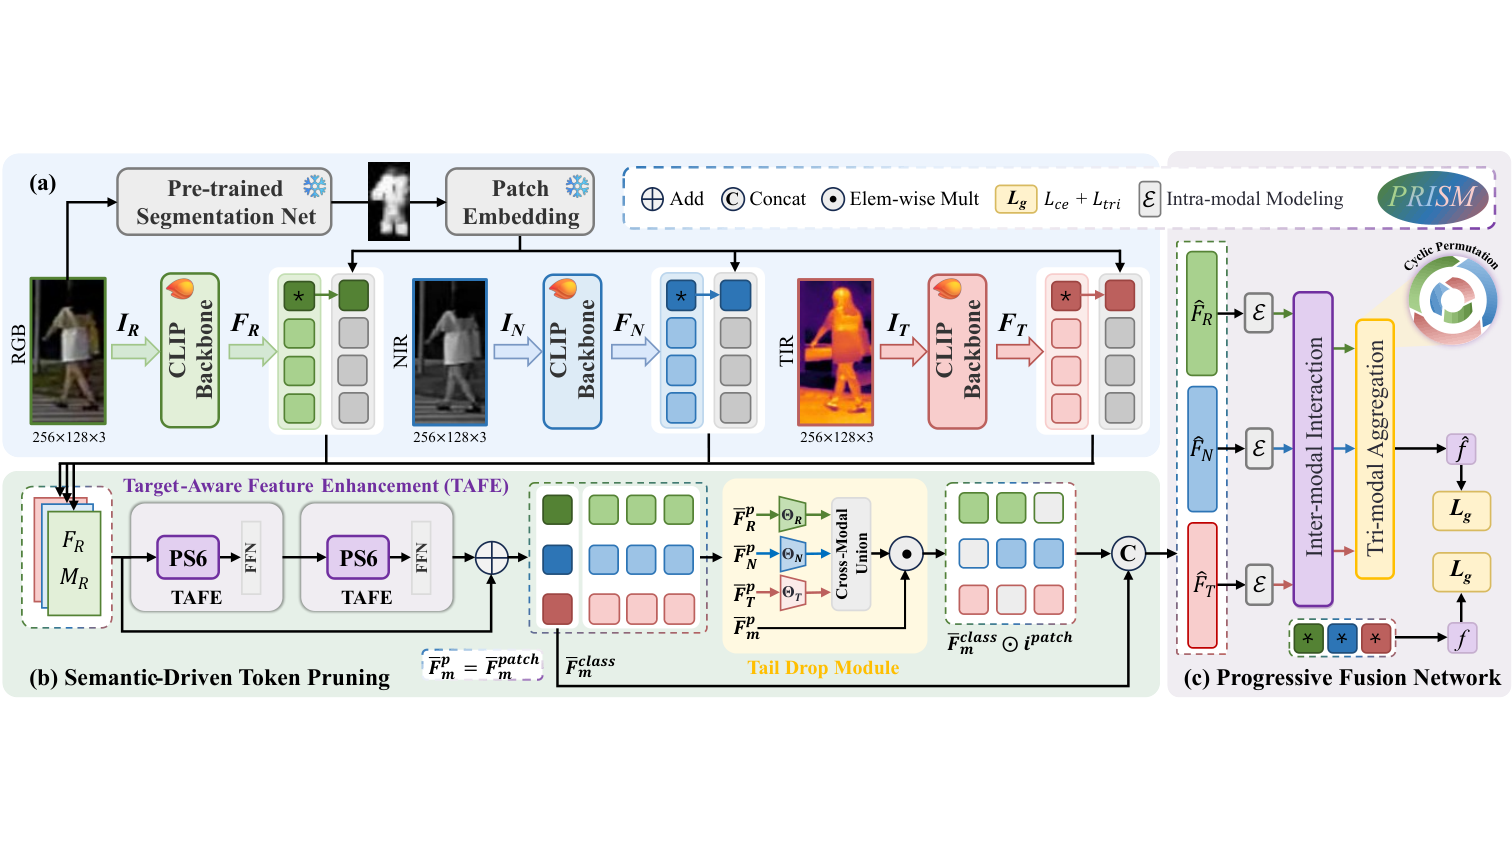
Multi-Modal Object Re-Identification with Prompt-S6 and Semantic-Aware Knowledge Guidance
IEEE Transactions on Image Processing (TIP)
PRISM combines Prompt-S6, semantic-driven token pruning, and progressive fusion for efficient tri-modal object ReID.
Why this work matters
Uses segmentation-model priors to suppress background tokens while preserving linear-complexity cross-modal interaction.
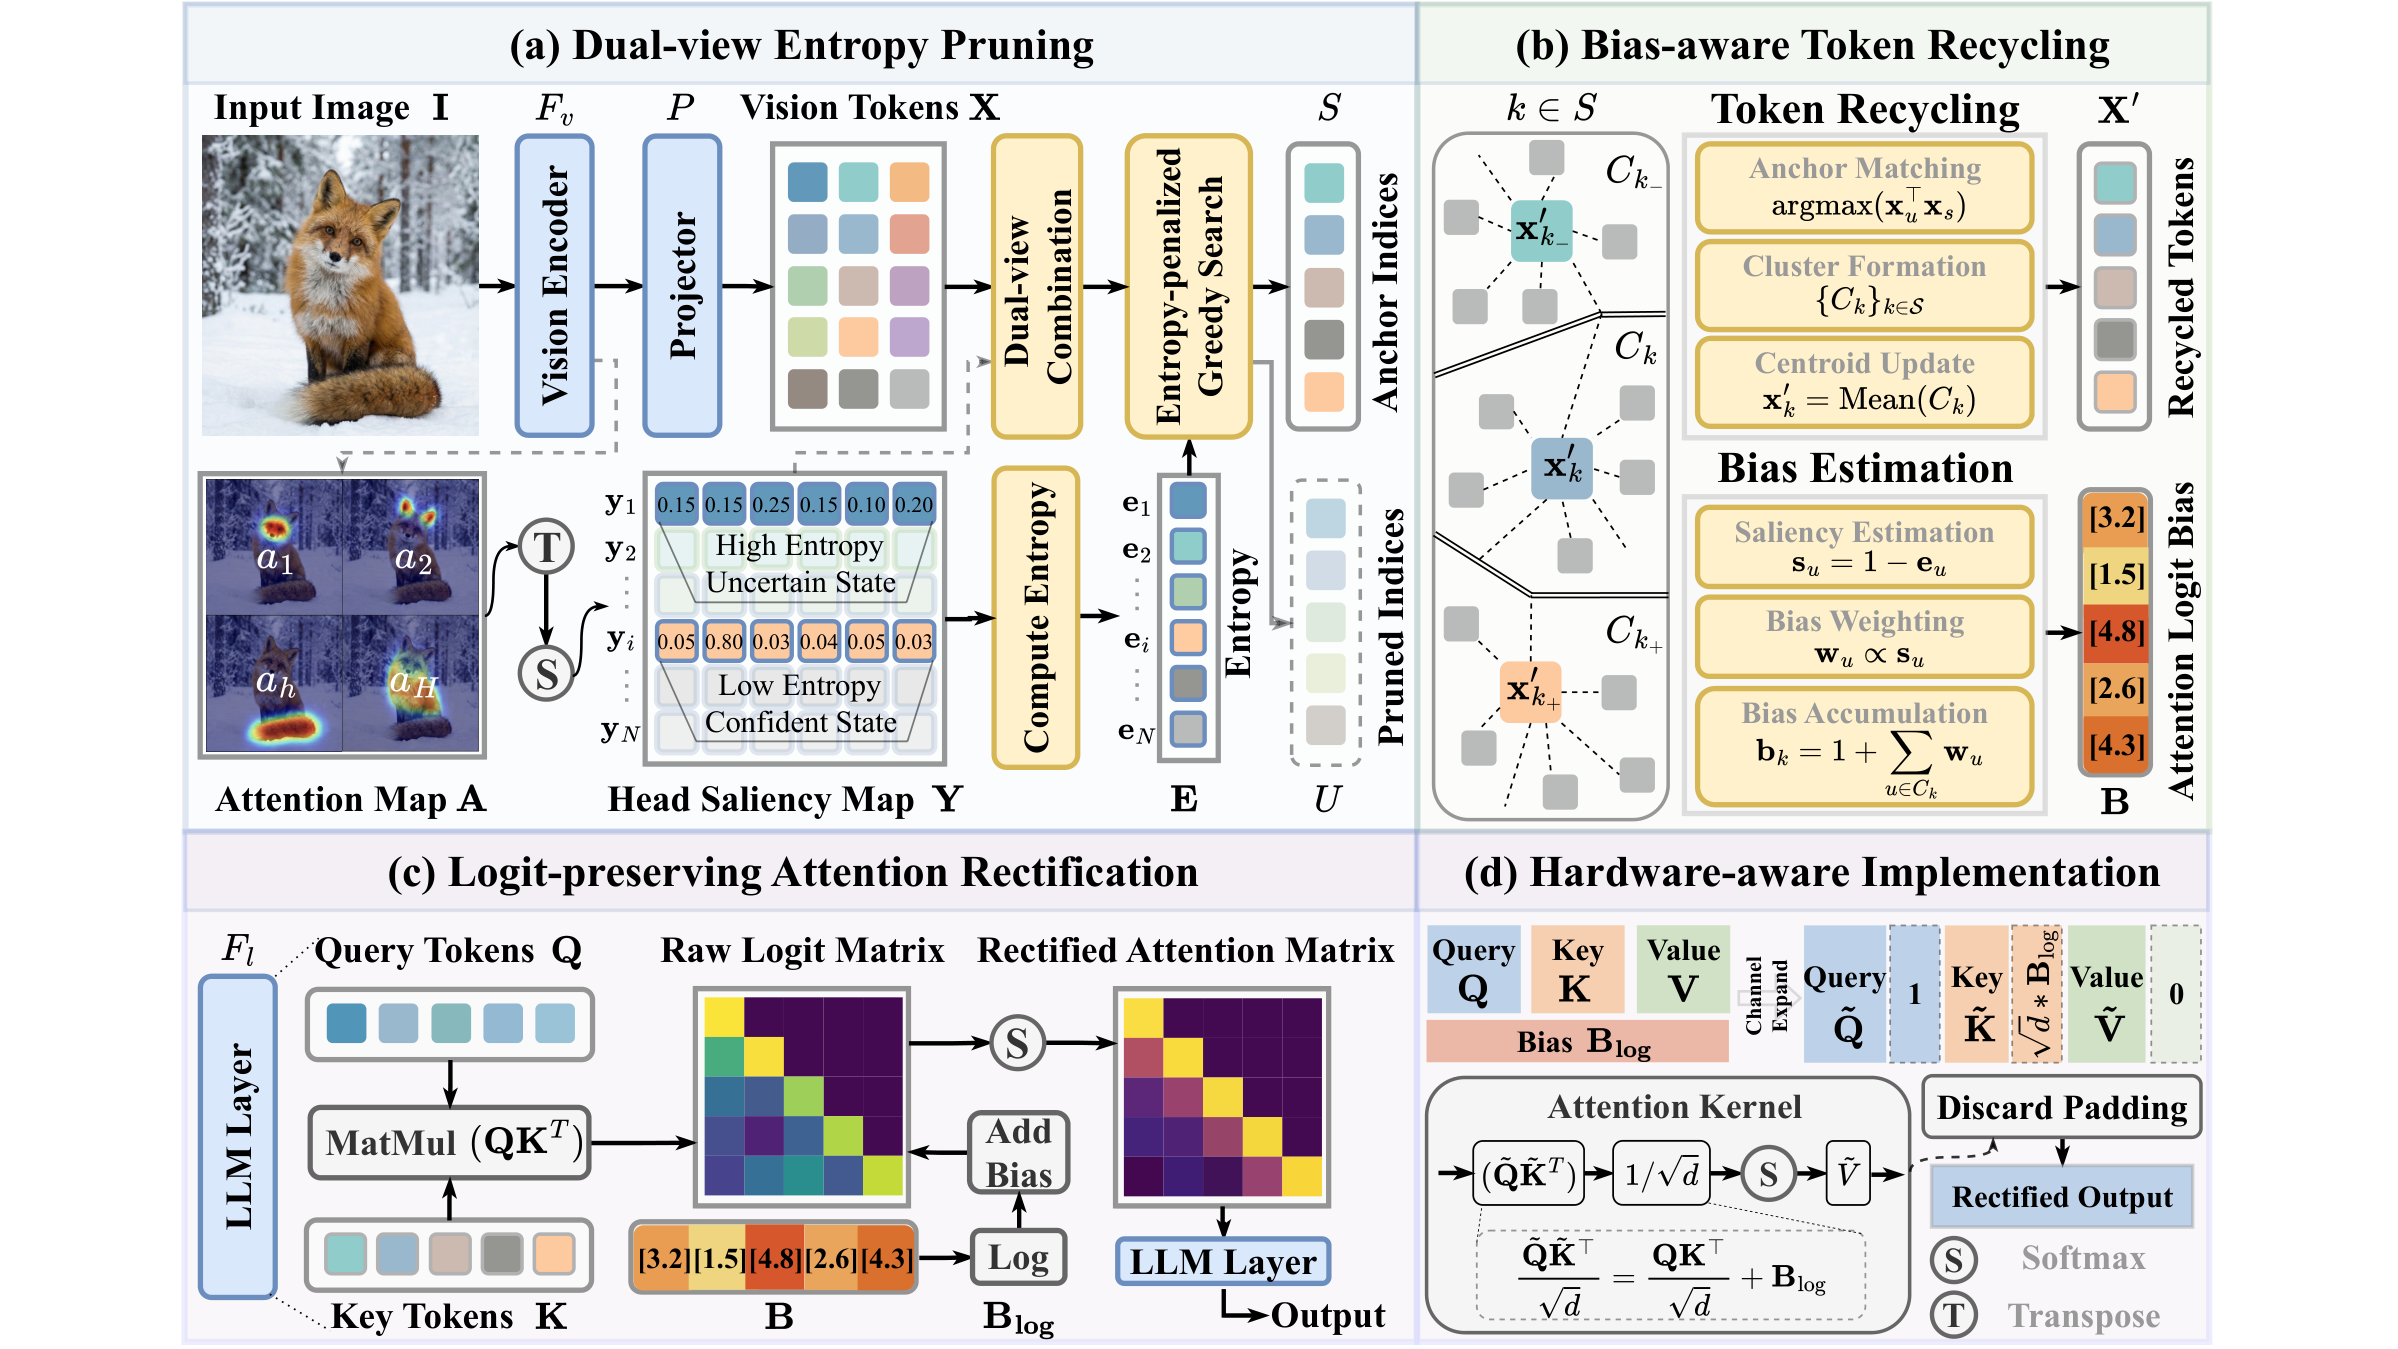
ERA: Entropy-Guided Visual Token Pruning with Rectified Attention for Efficient MLLMs
arXiv preprint
An entropy-guided, training-free pruning framework that preserves visual evidence by rectifying attention-logit collapse after token reduction.
Why this work matters
ERA unifies head-wise entropy pruning, bias-aware token recycling, and logit-preserving attention rectification across single-image, multi-image, video, and vLLM serving settings.
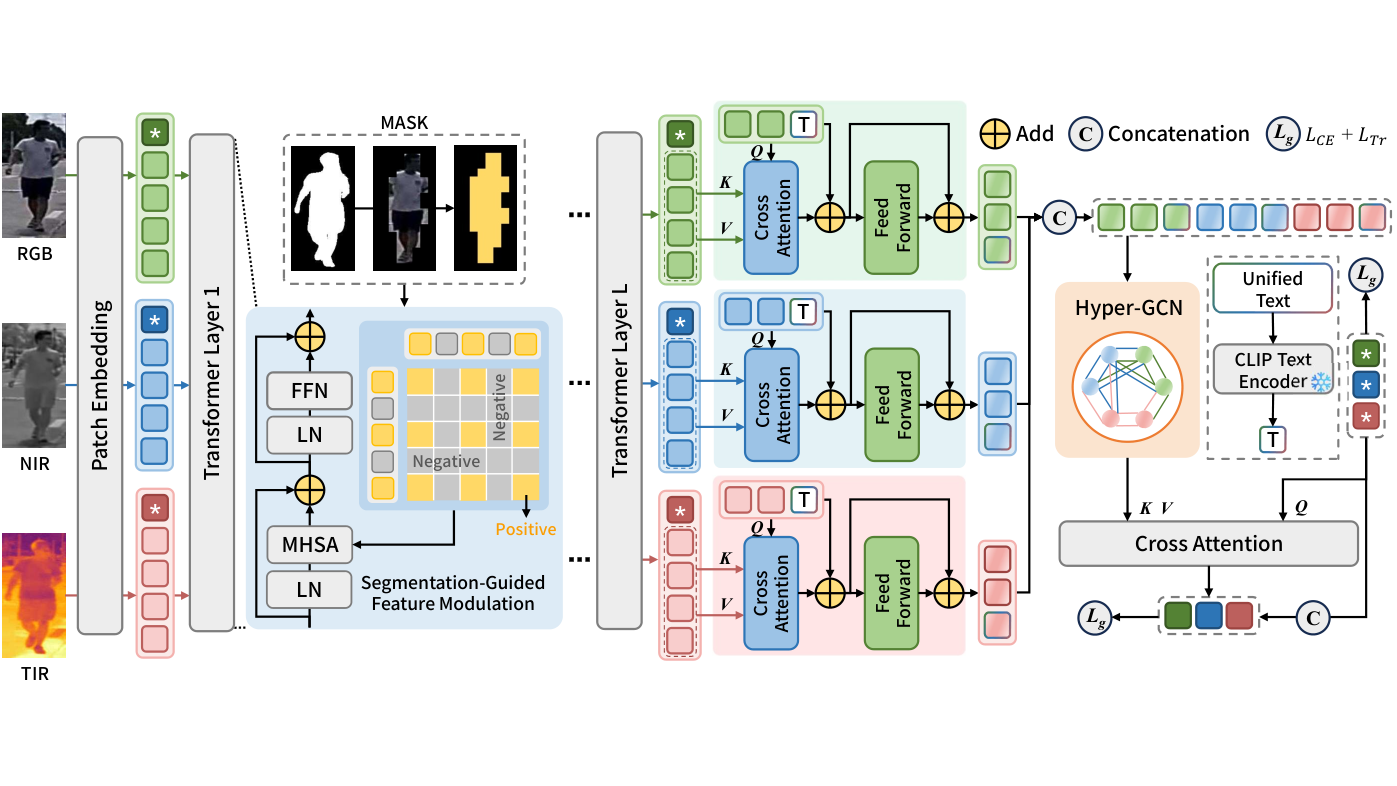
STMI: Segmentation-Guided Token Modulation with Cross-Modal Hypergraph Interaction for Multi-Modal Object Re-Identification
AAAI Conference on Artificial Intelligence (AAAI)
Segmentation priors modulate foreground tokens while a cross-modal hypergraph captures higher-order RGB/NIR/TIR relations.
Why this work matters
Uses SAM-guided token redistribution and unified hypergraph interaction without relying on hard foreground deletion.
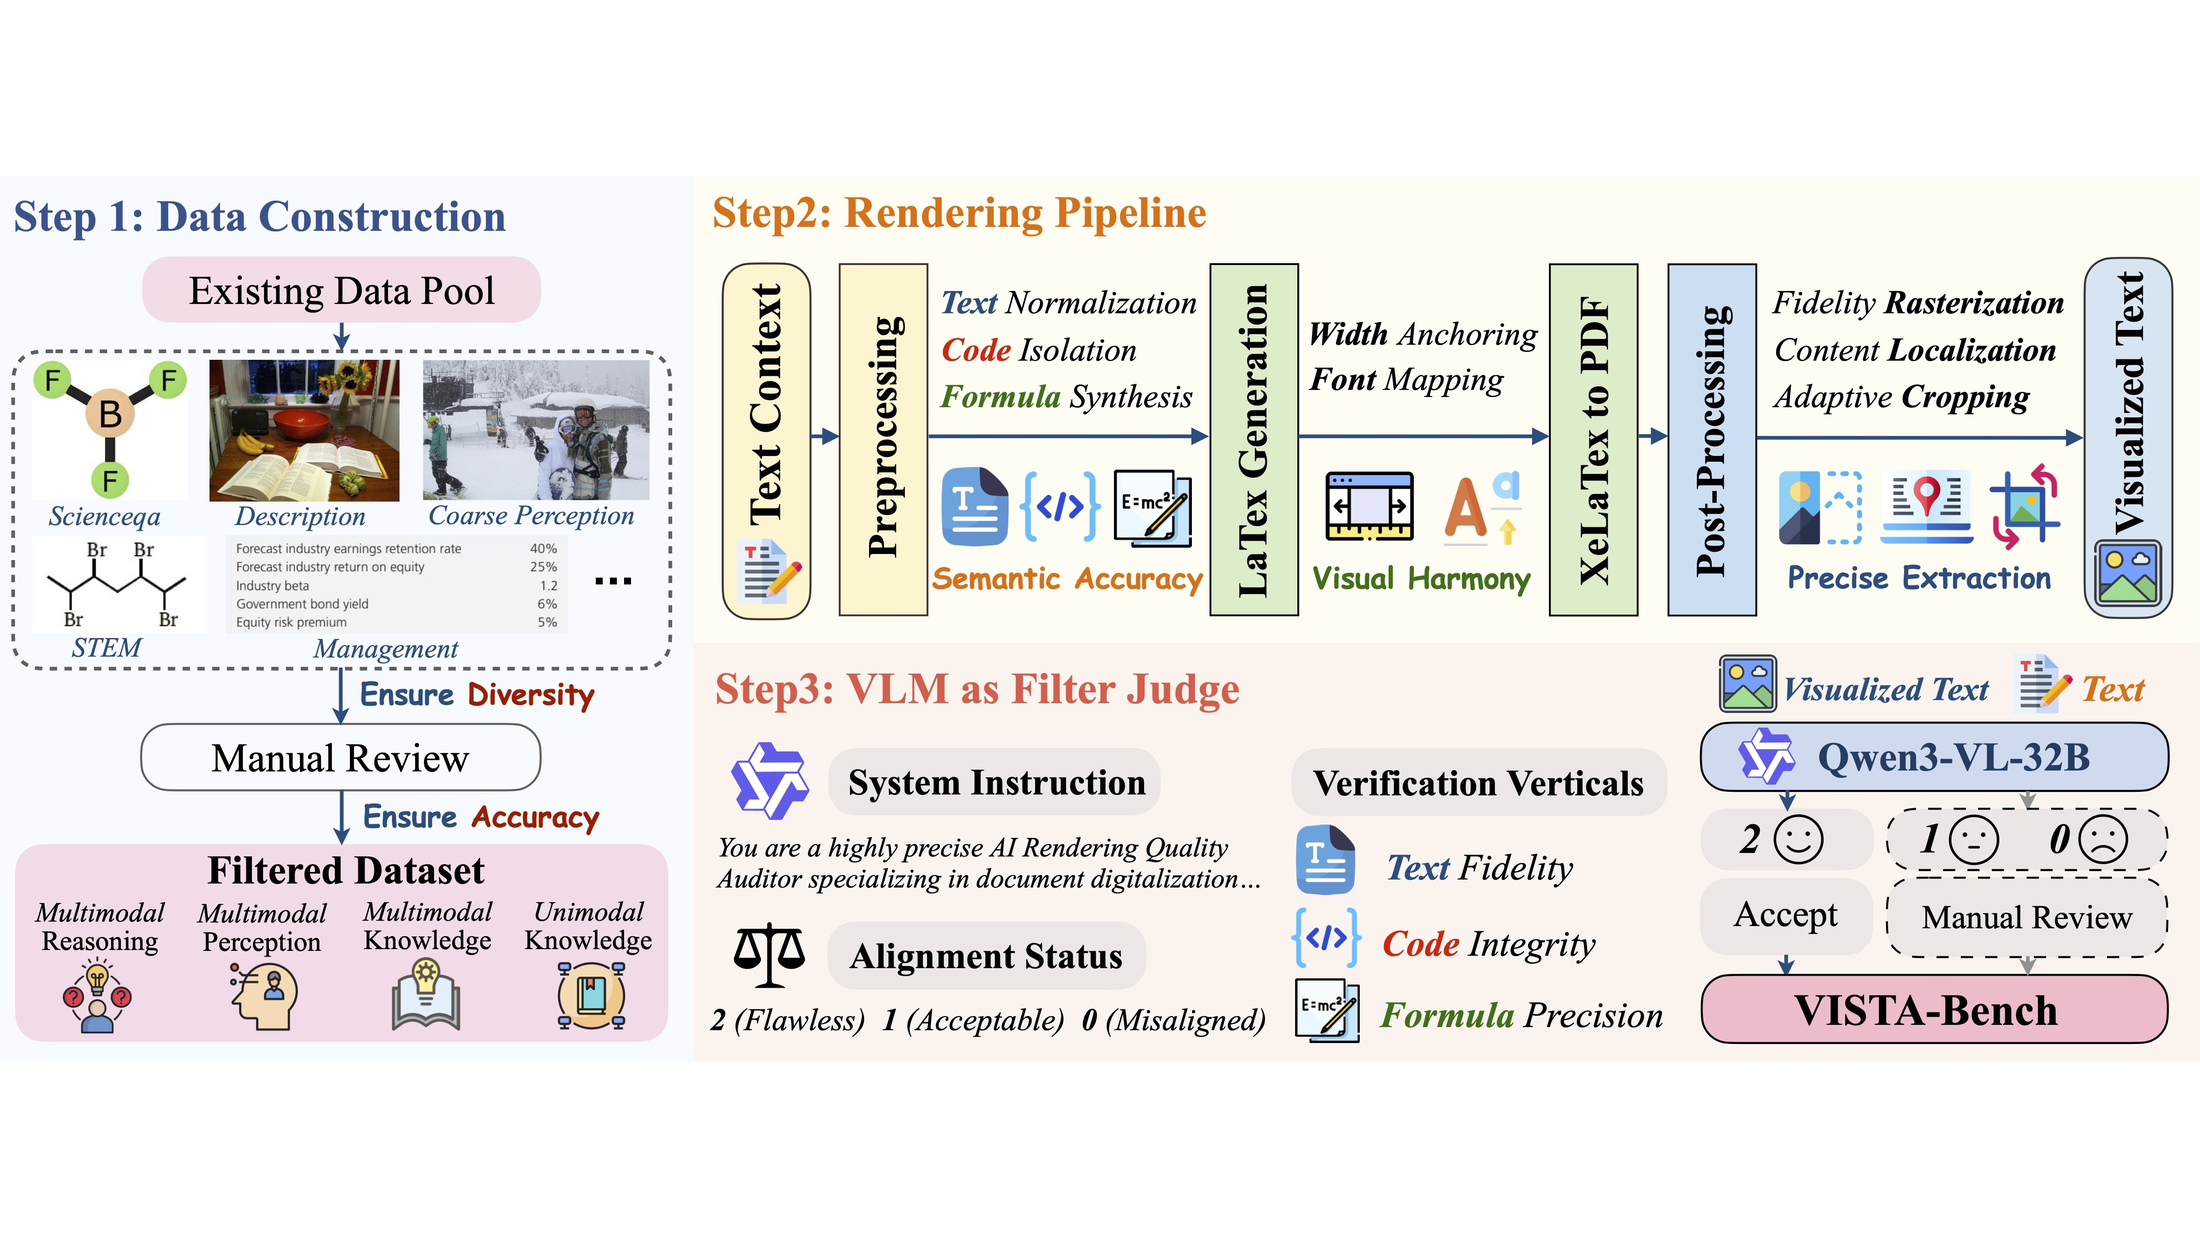
VISTA-Bench: Do Vision-Language Models Really Understand Visualized Text as Well as Pure Text?
arXiv preprint
A paired benchmark testing whether VLMs understand visualized text as reliably as equivalent pure text.
Why this work matters
Builds 1,500 paired items and evaluates more than 30 VLMs, exposing a modality gap that widens with rendering difficulty.
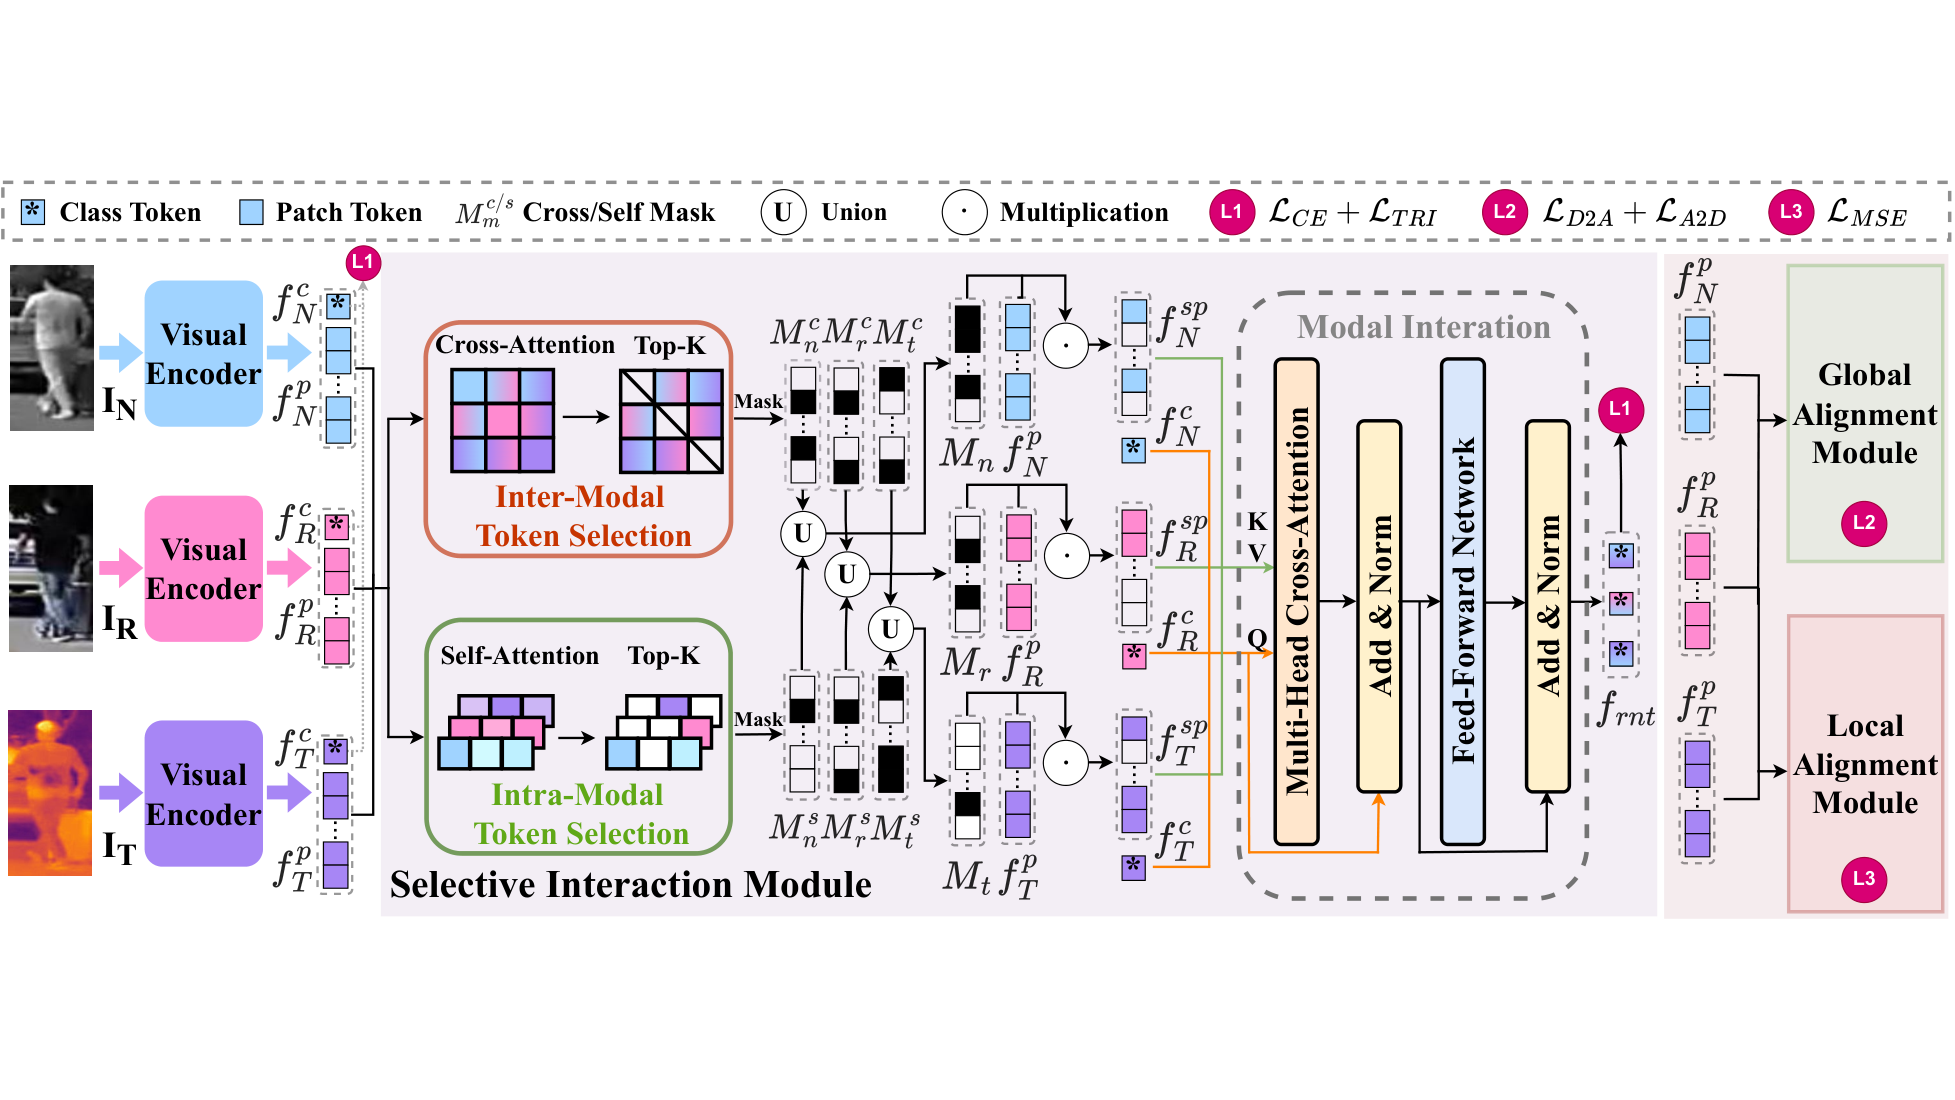
Signal: Selective Interaction and Global-local Alignment for Multi-Modal Object Re-Identification
AAAI Conference on Artificial Intelligence (AAAI)
Selective patch interaction and joint global-local alignment suppress background interference and improve consistency across three visual modalities.
Why this work matters
Introduces selective interaction, Gramian-space global alignment, and shift-aware local alignment for multimodal object ReID.
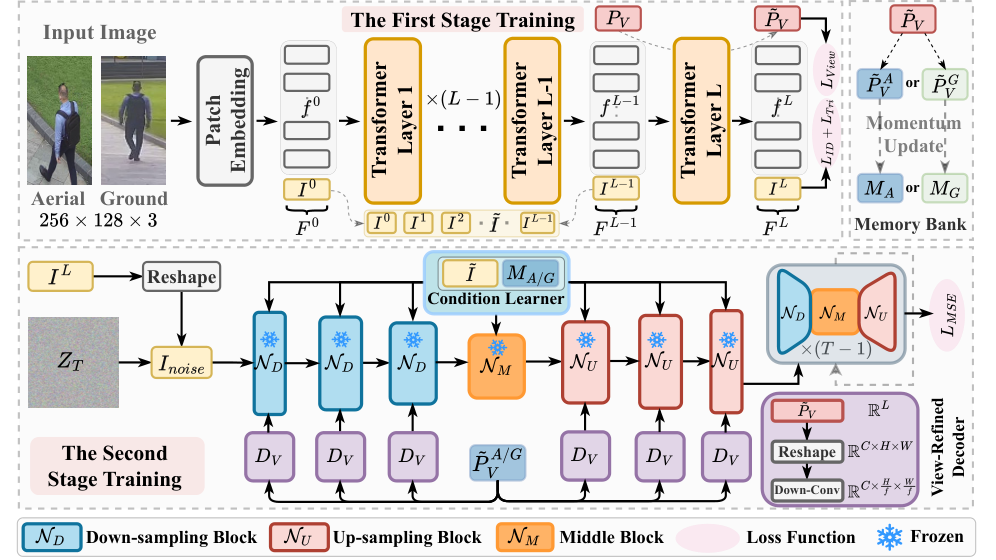
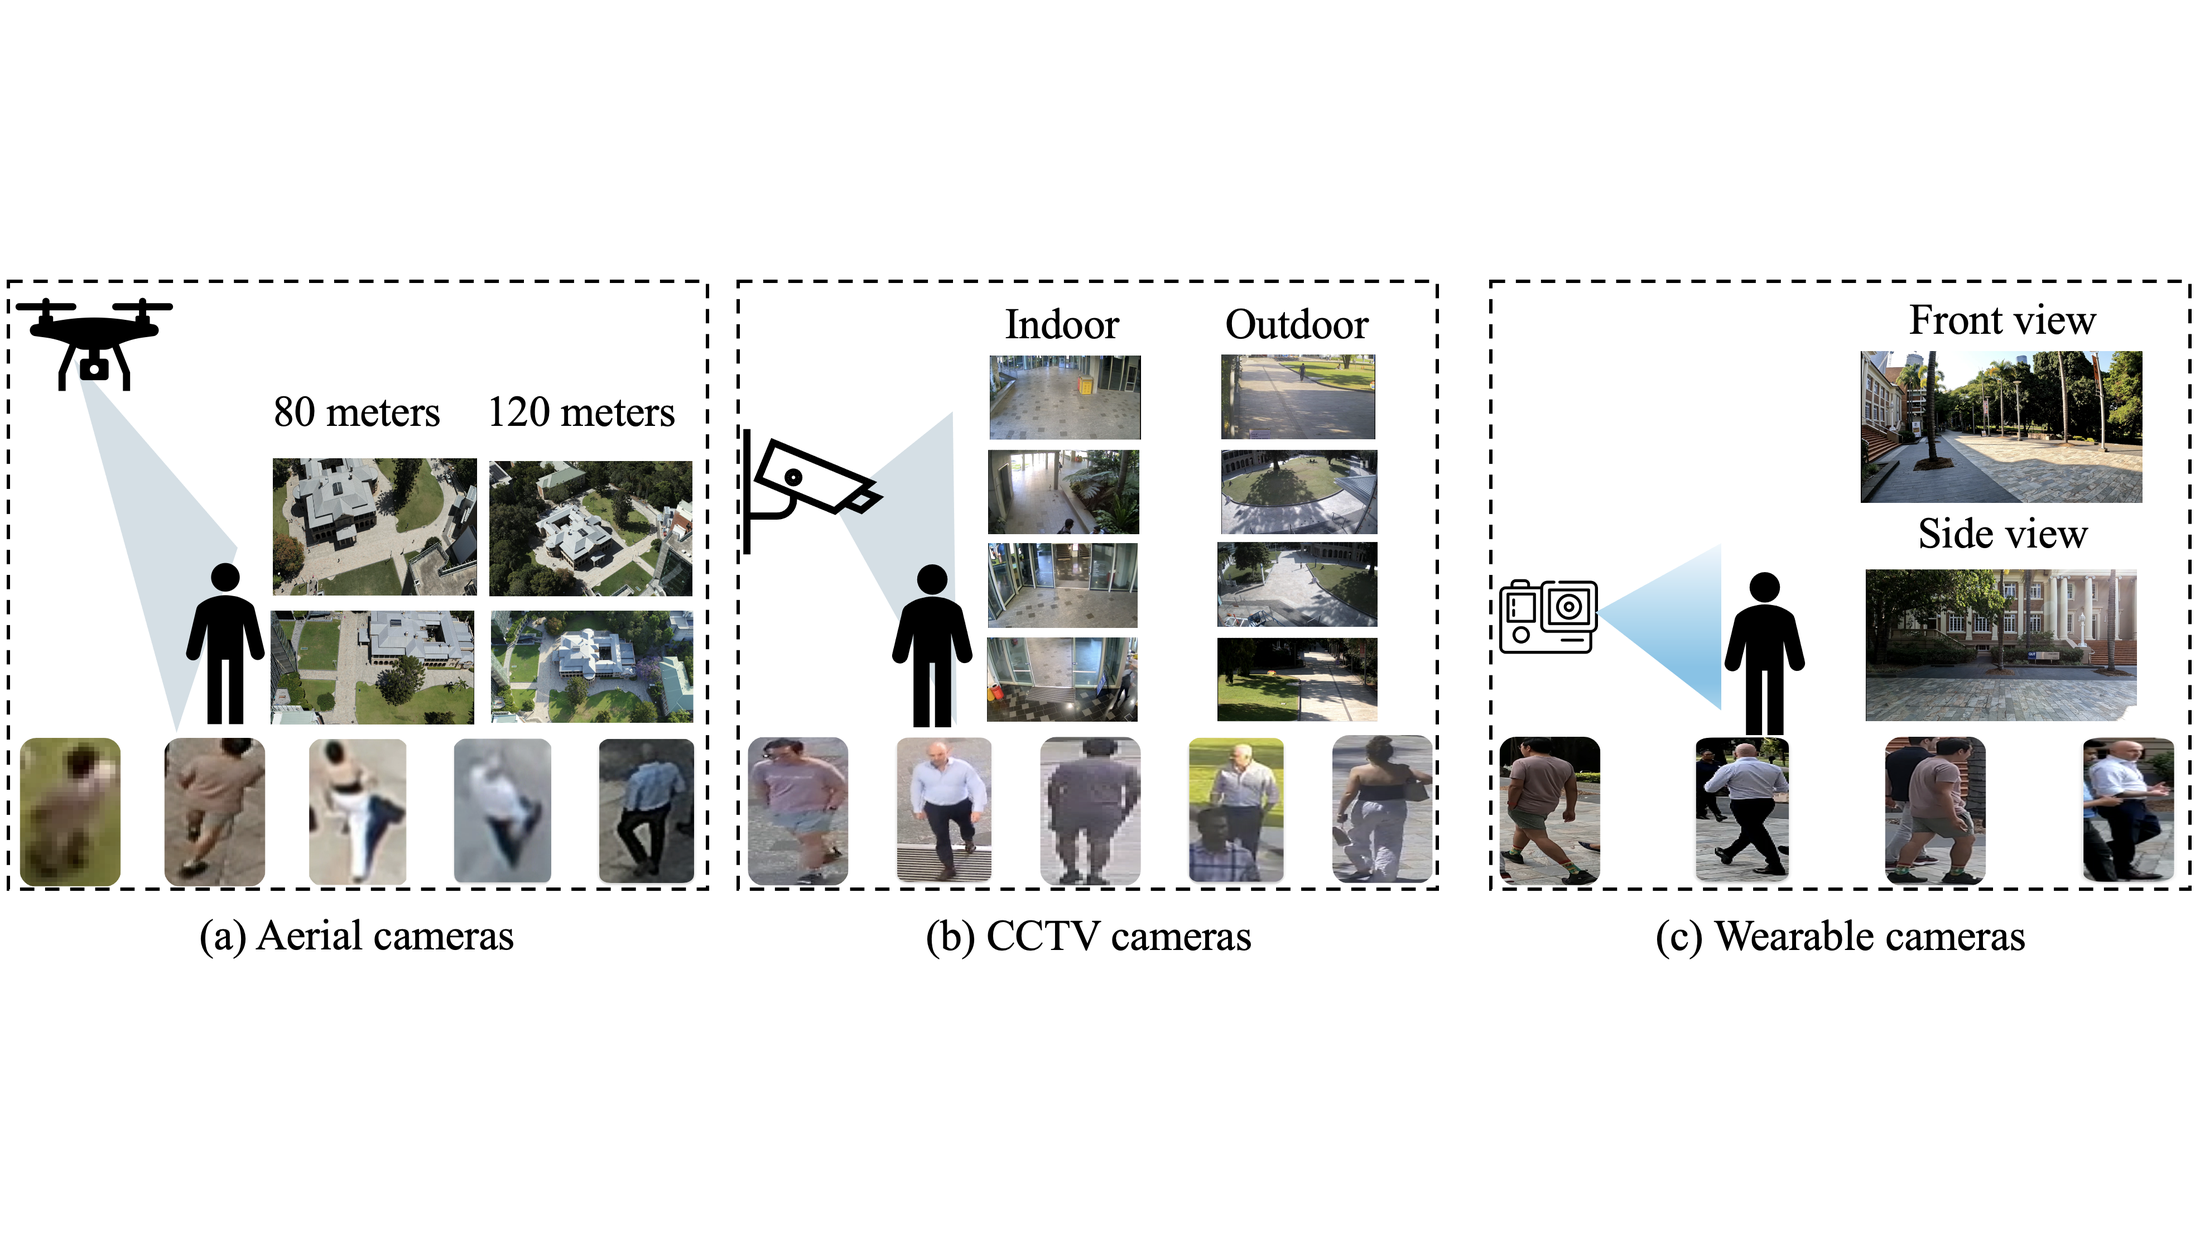
SD-ReID: View-aware Stable Diffusion for Aerial-Ground Person Re-Identification
IEEE Transactions on Image Processing (TIP)
A view-aware generative framework that uses controllable diffusion priors to improve identity consistency across aerial and ground cameras.
Why this work matters
Models view-specific feature distributions with a controllable Stable Diffusion model and a view-refined decoder across five aerial-ground ReID benchmarks.
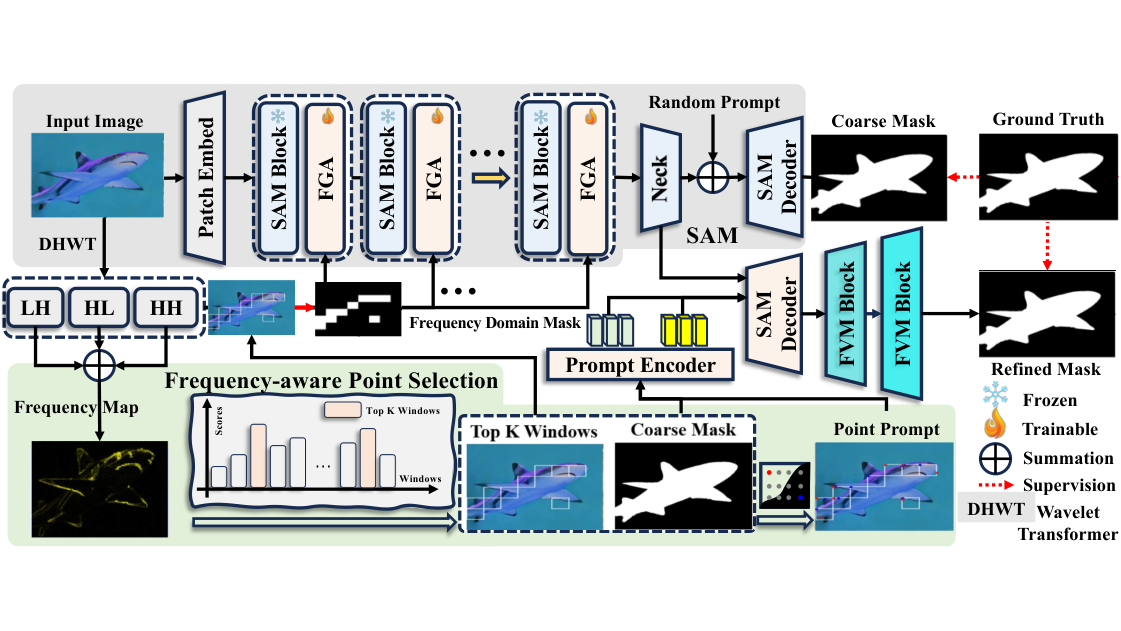
HFP-SAM: Hierarchical Frequency Prompted SAM for Efficient Marine Animal Segmentation
IEEE Transactions on Image Processing (TIP)
Frequency-domain priors and full-view Mamba adapt SAM to fine-grained marine animal segmentation under complex underwater noise.
Why this work matters
Combines a frequency-guided adapter, frequency-aware point selection, and linear-complexity contextual modeling.
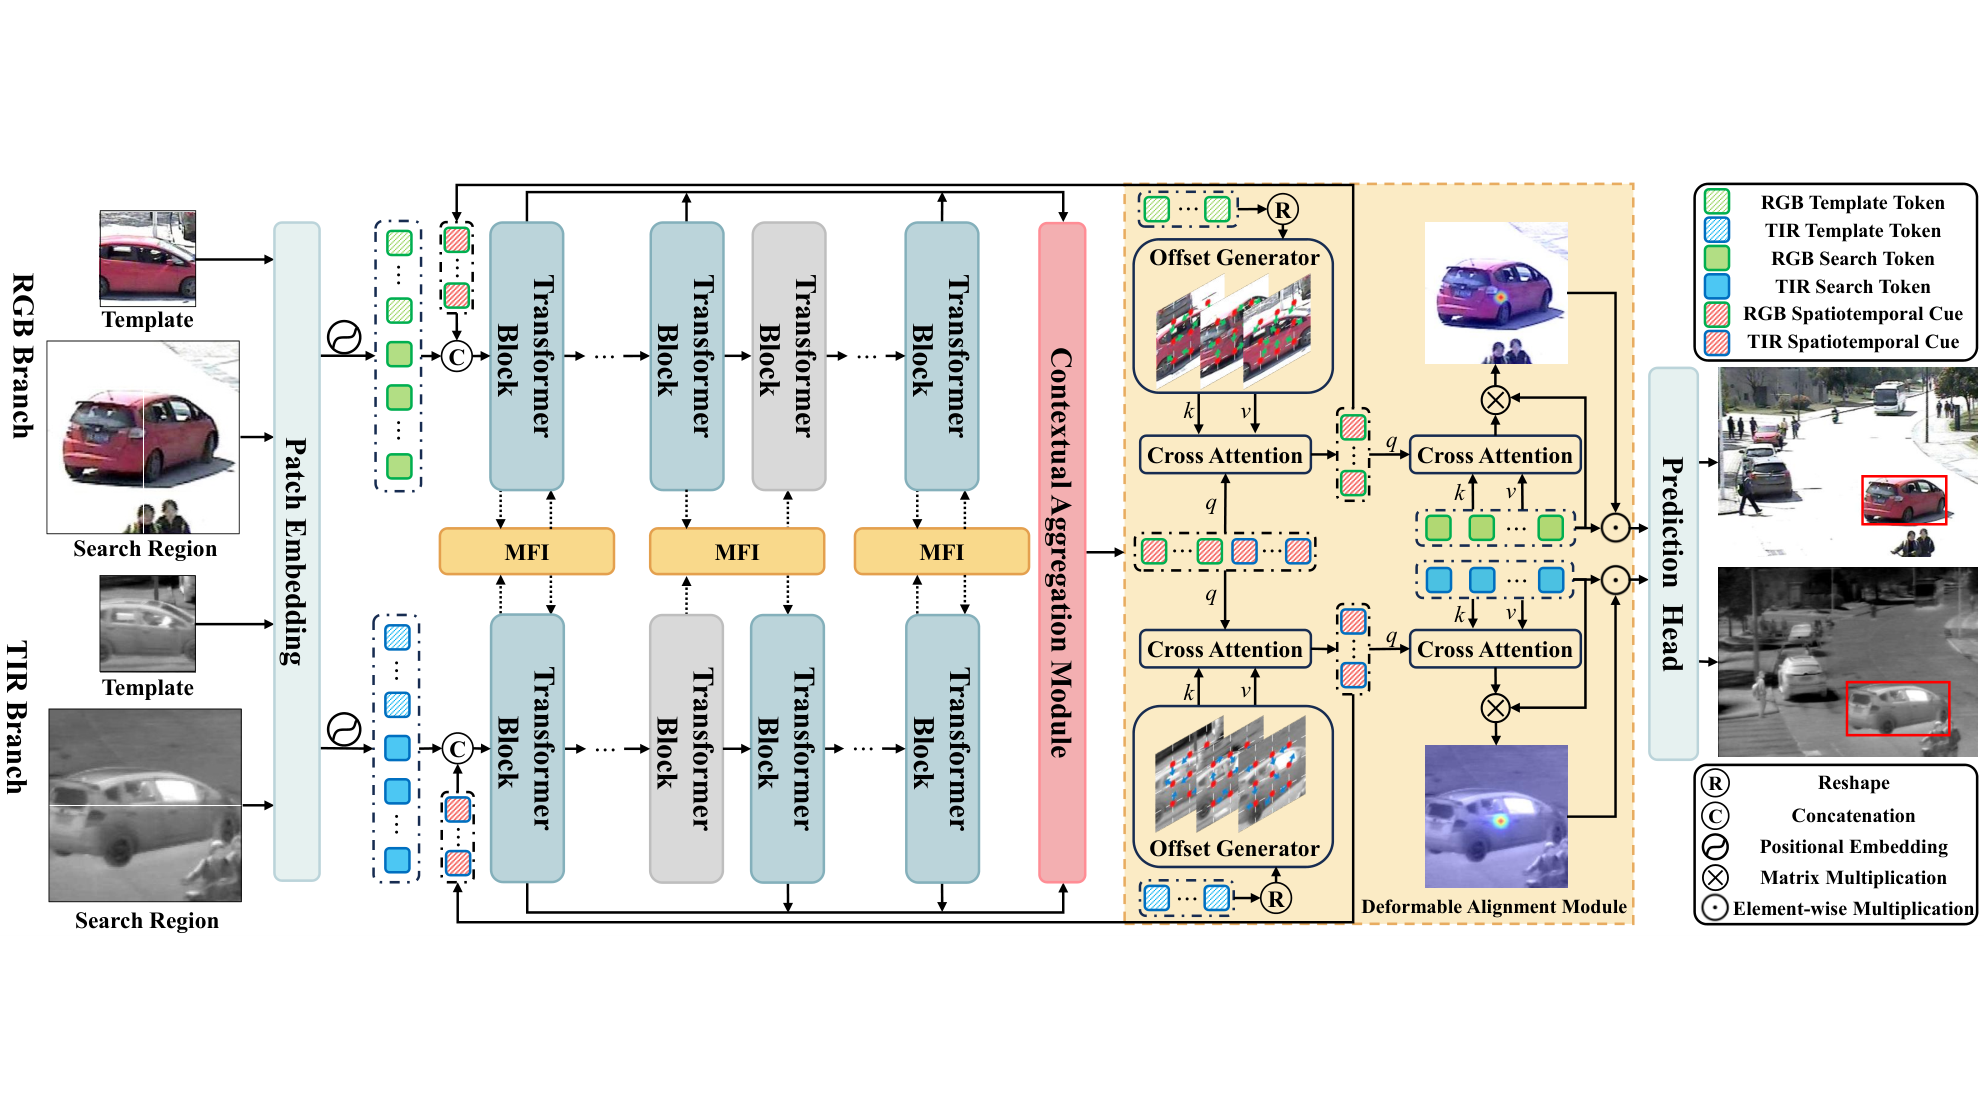
CADTrack: Learning Contextual Aggregation with Deformable Alignment for Robust RGBT Tracking
AAAI Conference on Artificial Intelligence (AAAI)
Contextual aggregation and deformable alignment improve robust visual tracking across visible and thermal modalities.
Why this work matters
Combines linear-complexity cross-modal interaction, sparse expert aggregation, and deformable temporal alignment.
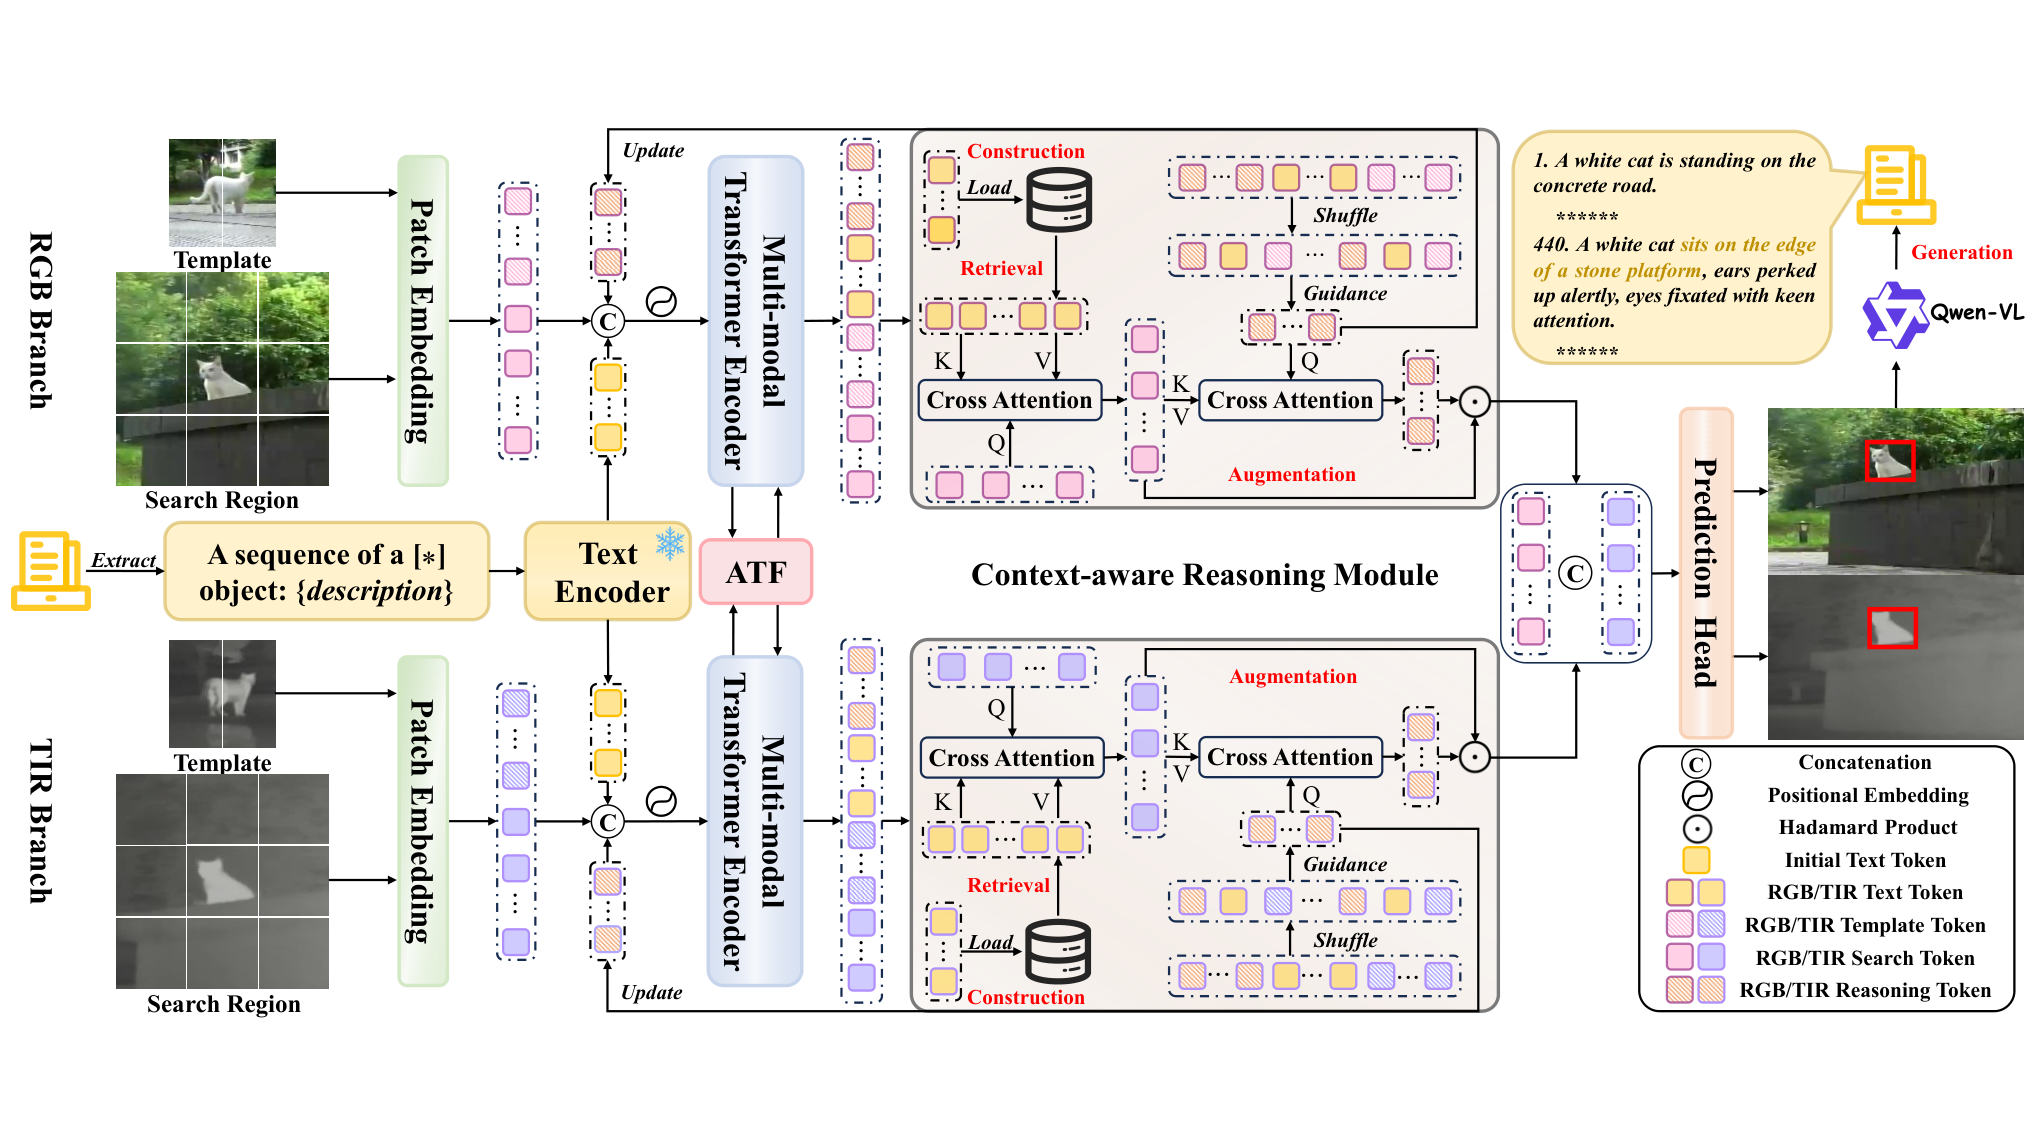
RAGTrack: Language-aware RGBT Tracking with Retrieval-Augmented Generation
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)
Introduces MLLM-generated language and retrieval-augmented temporal reasoning into visible-thermal object tracking.
Why this work matters
Builds text-enhanced RGBT benchmarks and combines adaptive token fusion with a dynamic visual-language knowledge base.
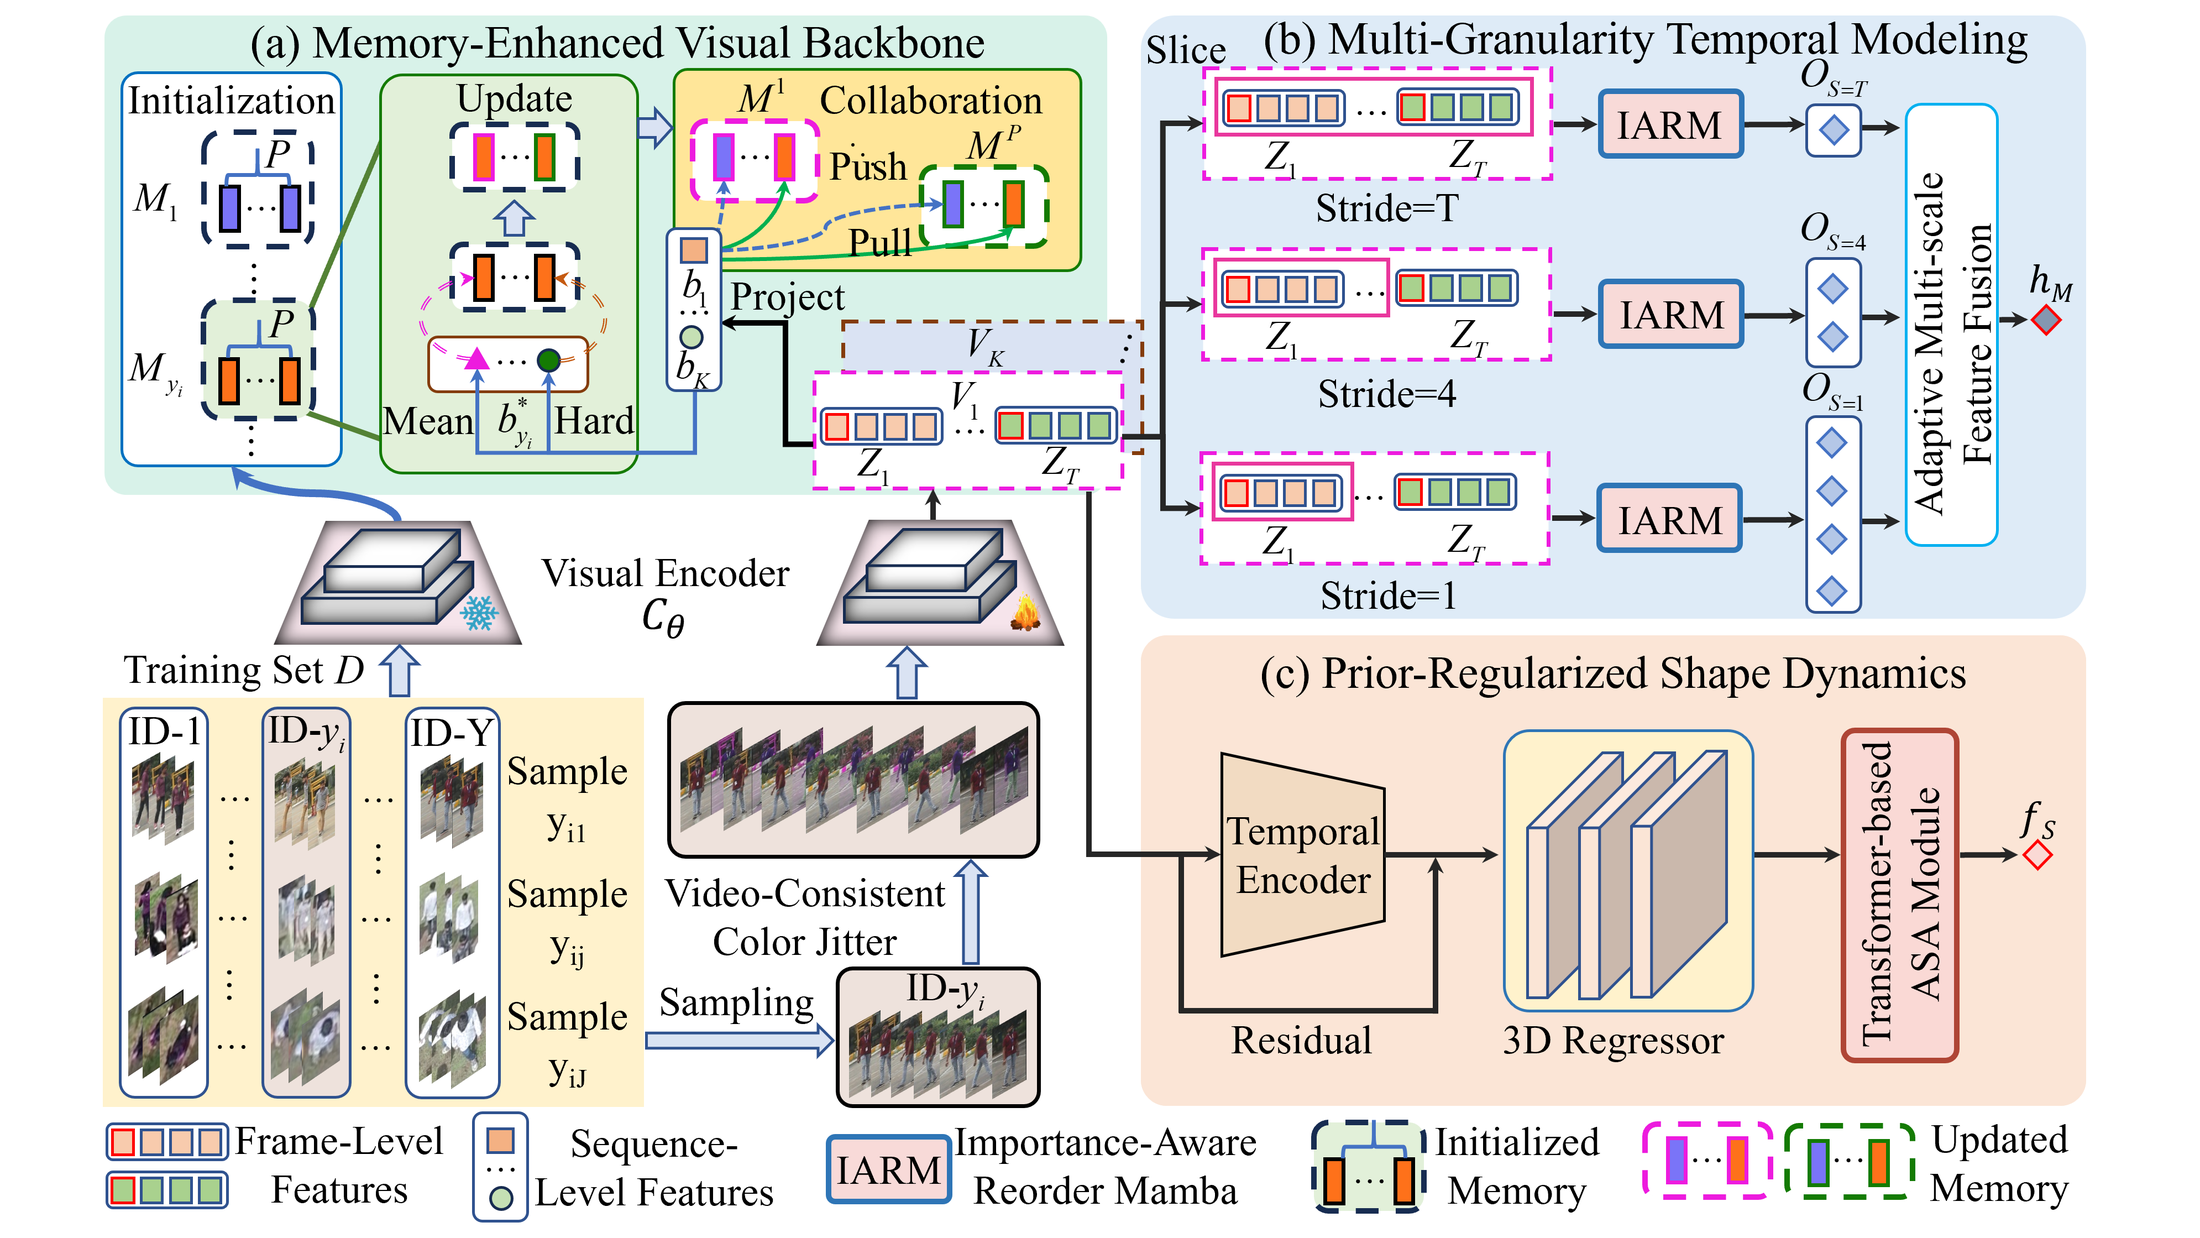
SAS-VPReID: A Scale-Adaptive Framework with Shape Priors for Video-based Person Re-Identification at Extreme Far Distances
WACV Workshop on Video Re-Identification at Extreme Far Distances
A scale-adaptive video ReID framework combining low-resolution enhancement, multiscale temporal modeling, and clothing-robust shape priors.
Why this work matters
The DLUT challenge solution ranked first in the associated extreme-far-distance video ReID track.
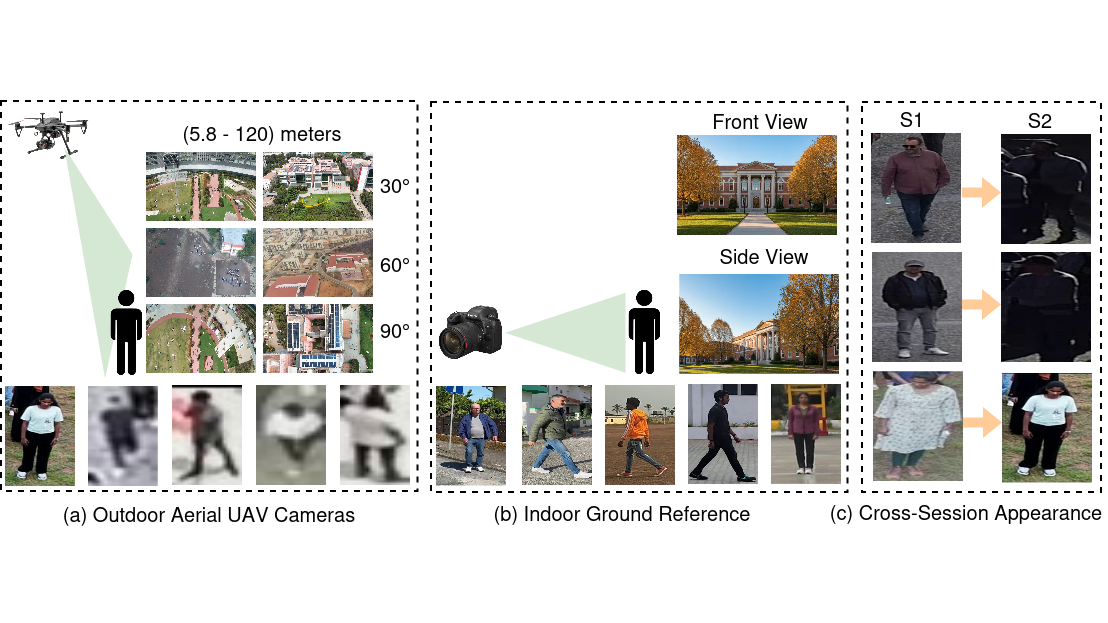

IDEA: Inverted Text with Cooperative Deformable Aggregation for Multi-Modal Object Re-Identification
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)
A text-guided multimodal framework that uses cooperative deformable aggregation to bridge visual and language cues for object re-identification.
Why this work matters
Constructs three MLLM-generated text-enhanced benchmarks and introduces inverted semantic guidance with adaptive local feature sampling.
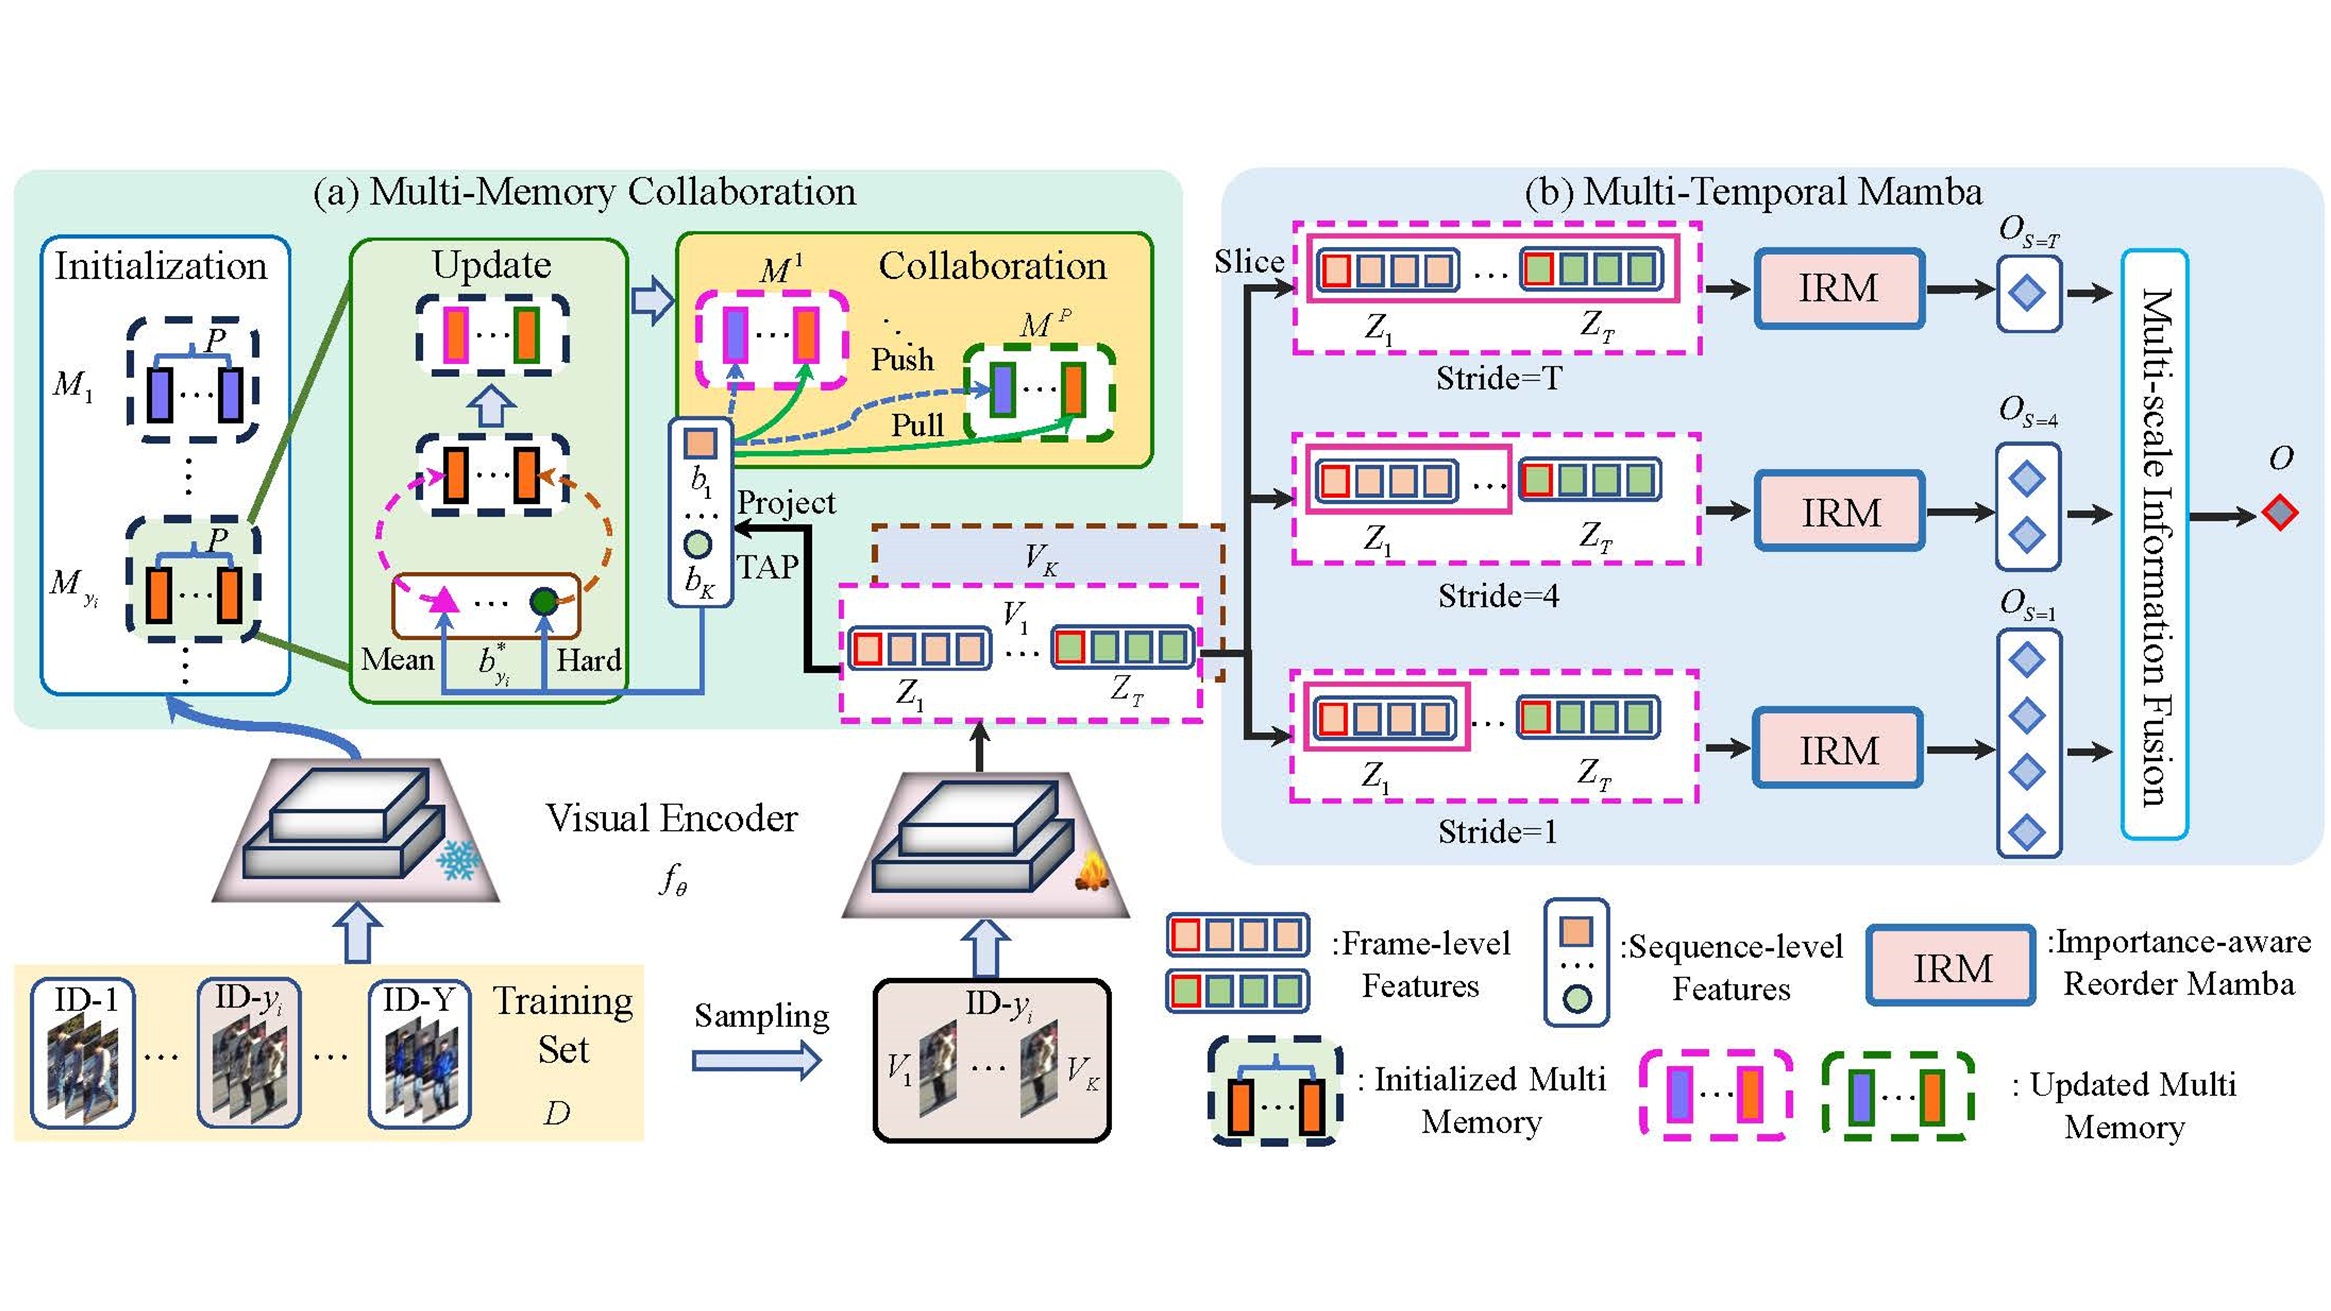
CLIMB-ReID: A Hybrid CLIP-Mamba Framework for Person Re-Identification
AAAI Conference on Artificial Intelligence (AAAI)
A hybrid CLIP–Mamba framework for transferring language-aligned visual representations to person re-identification.
Why this work matters
Combines CLIP semantics with Mamba sequence modeling for efficient person representation.
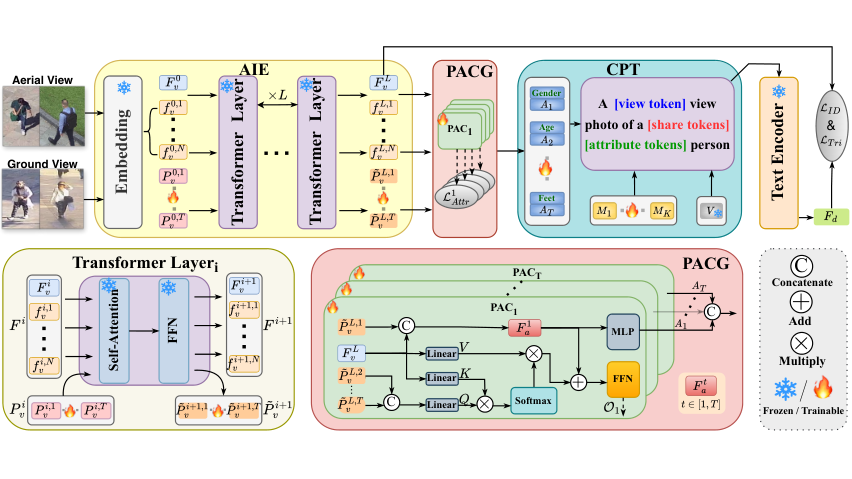
LATex: Leveraging Attribute-based Text Knowledge for Aerial-Ground Person Re-Identification
arXiv preprint
A parameter-efficient CLIP prompt-tuning framework that turns stable person attributes and camera viewpoints into structured text guidance.
Why this work matters
Introduces attribute-aware image encoding, prompted attribute classification, and coupled text prompts for aerial-ground ReID.

Unity Is Strength: Unifying Convolutional and Transformeral Features for Better Person Re-Identification
IEEE Transactions on Intelligent Transportation Systems (TITS)
A hybrid representation that combines convolutional locality with Transformer context for robust person re-identification.
Why this work matters
Unifies local convolutional cues and global Transformer features rather than treating the two architecture families as alternatives.

DeMo: Decoupled Feature-Based Mixture of Experts for Multi-Modal Object Re-Identification
AAAI Conference on Artificial Intelligence (AAAI)
A decoupled mixture-of-experts design that routes complementary modality features for more reliable multimodal object matching.
Why this work matters
Preserves modality-specific knowledge through hierarchical feature decoupling and replaces static expert gates with attention-triggered routing.

MambaPro: Multi-Modal Object Re-Identification with Mamba Aggregation and Synergistic Prompt
AAAI Conference on Artificial Intelligence (AAAI)
A Mamba-based aggregation and prompt learning framework for modeling long-range multimodal dependencies in object re-identification.
Why this work matters
Adapts CLIP with parallel feed-forward adapters, synergistic residual prompts, and linear-complexity Mamba aggregation.

Sigma: Siamese Mamba Network for Multi-Modal Semantic Segmentation
IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)
A Siamese Mamba architecture for fusing complementary modalities in dense semantic prediction.
Why this work matters
Introduces Siamese state-space modeling for efficient long-range interaction in multimodal semantic segmentation.
VMambaX: Exploiting Vision Mamba for Abdominal X-ray Image Based NEC Classification
Manuscript

TOP-ReID: Multi-spectral Object Re-Identification with Token Permutation
AAAI Conference on Artificial Intelligence (AAAI)
A token permutation approach for learning identity-aware representations across visible and infrared spectra.
Why this work matters
Uses token permutation to promote both cross-modal interaction and modality-specific representation.

Magic Tokens: Select Diverse Tokens for Multi-Modal Object Re-Identification
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)
A token selection strategy that preserves diverse, identity-relevant cues for multimodal object re-identification.
Why this work matters
Selects compact, diverse identity tokens before multimodal interaction to reduce background redundancy.
Publication policy. Published work, work under review, and ongoing research are deliberately separated. Missing links are omitted rather than replaced with placeholders. Latest detailed metadata is verified against public records.